Andreas Haupt
Digital Fellows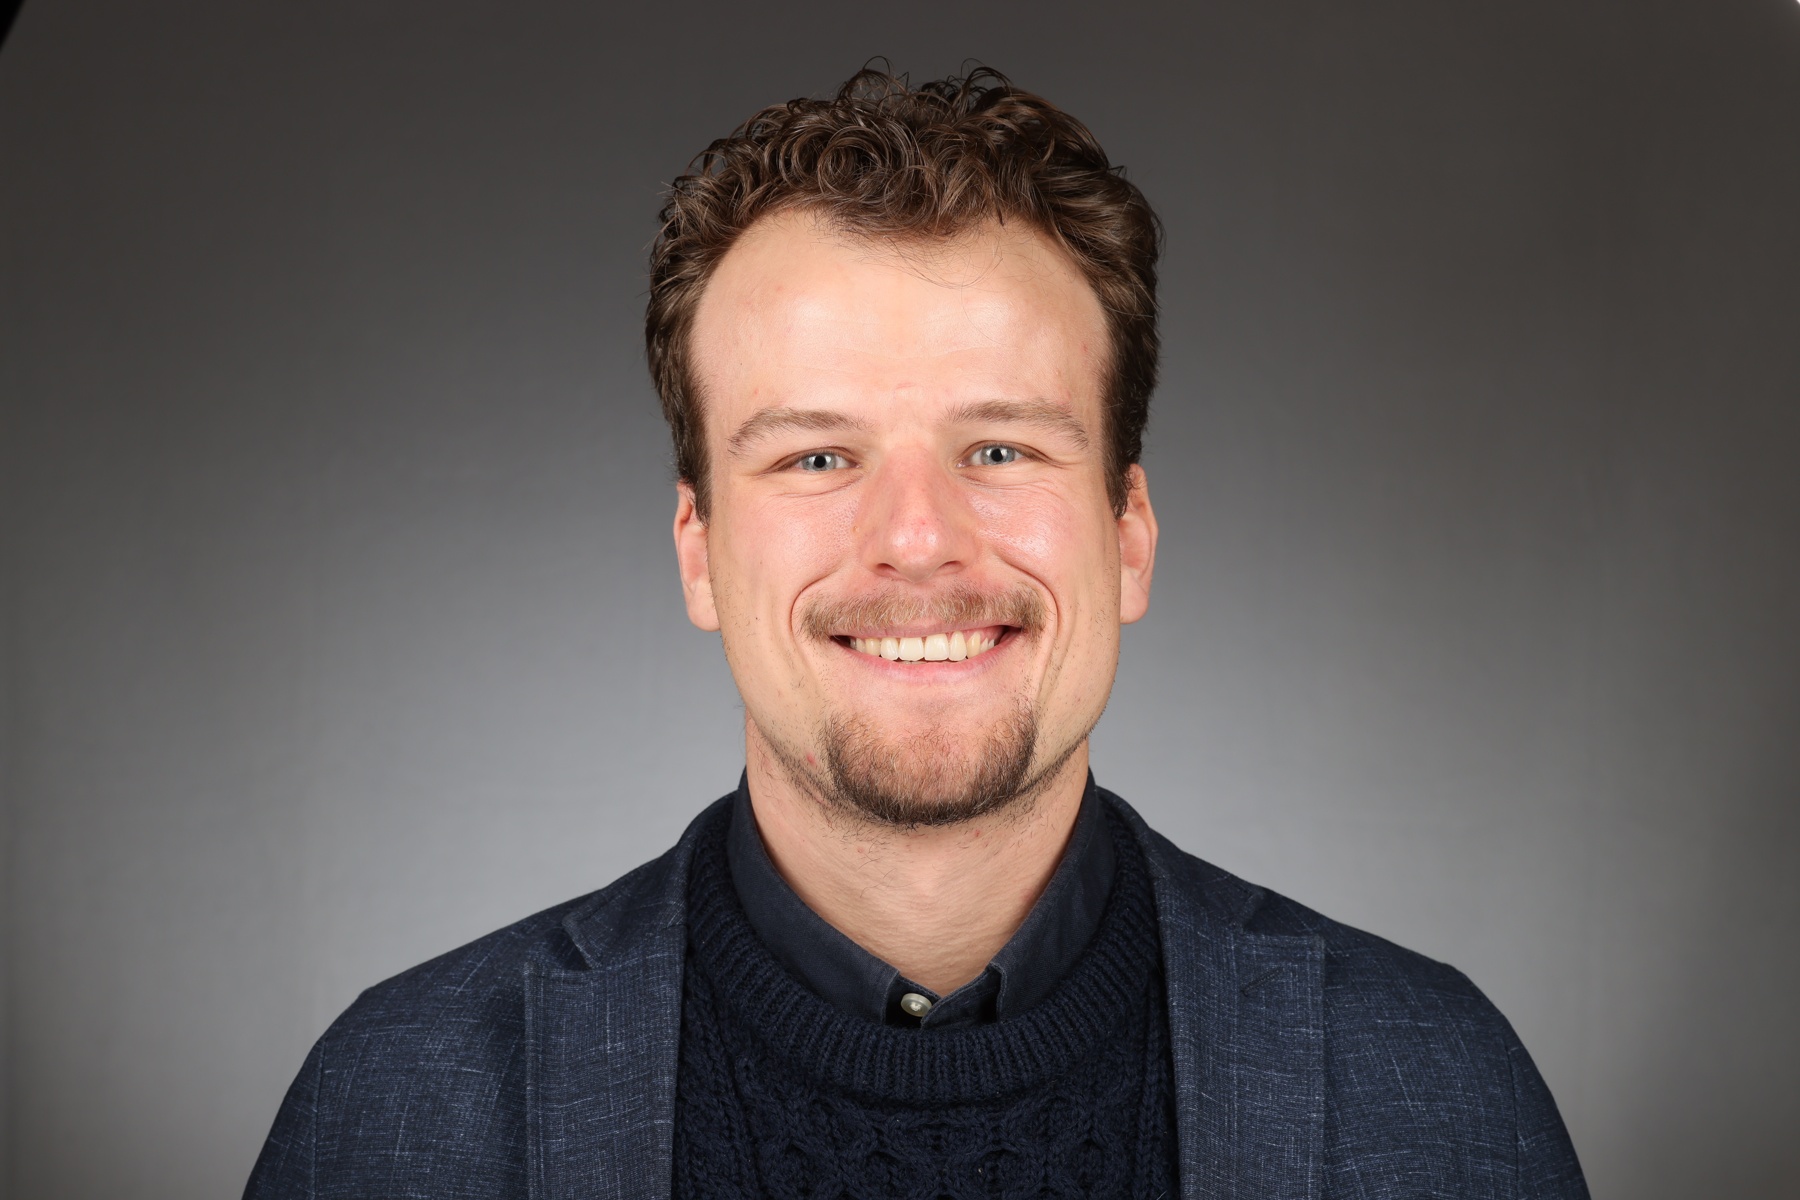
There’s such a long history on running randomized controlled trials in companies, and now everyone is evaluating AI. It felt too clear that we need to evaluate AI with the humans. That led to centaur evaluations.
Areas of Research
AISPA: User-Centric System Prompt Auditing for Large Language Model Applications
Authors:
Xiangning Lin et al.
TaskNet
Researchers:
Jennifer Wang, Andreas Haupt, Isaac Robinson, Phil Lewis, Erik Brynjolfsson, Diyi Yang, Adam Gill, Luca Vendraminelli, Andrew Wang, Natania Wong
Welfare, Improvability, and Variance: A Principal-Agent Approach to Optimal Benchmark Item Aggregation
Authors:
Andreas Haupt, Justin Hartenstein, Anka Reuel, Mykel Kochenderfer, Sanmi Koyejo